Memory and Performance
A game has one frame to do everything: 1/50 or 1/60 of a second. And its memory is counted in kilobytes. This chapter gathers what you need to know to write a fast, frugal program, on processors as different as the 6502, the Z80 and the 68000. Every figure was measured.
The frame budget
Everything a game does for one frame (read the joypad, move the characters, test collisions, update the screen, play the music) must fit in the time of one frame. Beyond that, the game slows down.
| Machine | Processor | Frames per second | Cycles per frame |
|---|---|---|---|
| Commodore 64 (PAL) | 6510 at 0.98 MHz | 50 | 19,656 |
| PC Engine | HuC6280 at 7.16 MHz | 60 | about 119,000 |
| NES | 2A03 at 1.79 MHz | 60 | about 29,800 |
| Amstrad CPC | Z80 at 4 MHz (effective: about 3.3) | 50 | 80,000 T-states, about 20,000 short instructions |
| Mega Drive | 68000 at 7.67 MHz | 60 | about 128,000 |
Cycles cannot be compared directly from one processor to another: an instruction takes 2 to 7 on a 6502, 4 to 23 on a Z80, 4 to more than 100 on a 68000. What matters is the share of the frame a computation takes.
Measure before you optimize
Optimize what is costly, not what you think is costly. The simplest technique, and the one programmers of the time used most: change the border color before a computation, and set it back afterward. The screen is drawn line by line while the program works: the height of the colored band shows the time spent.
// Measuring with the border: 20 divisions by 40 every frame (Commodore 64)
architecture commodore.c64;

addlib event.irq;
addlib vic.base;

unit {
    uint resultat;

    main() {
        vic.setBackgroundColor(vic.BLACK);
        while (1) {
            irq.waitFrame();                    // wait for the start of a frame
            vic.setBorderColor(vic.RED);        // the border in red during the computation...
            for (uint i = 0; i < 20; i++) {
                .resultat = (i + 1000) / 40;
            }
            vic.setBorderColor(vic.BLACK);      // ... then in black
        }
    }

    interrupt -> irq {
    }
}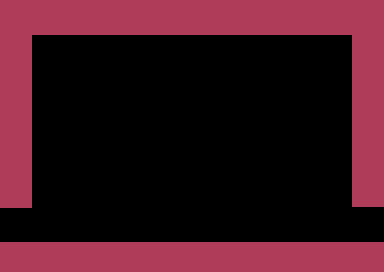
The same loop, with a single number changed, takes almost the whole frame in one case, and about thirty lines in the other. The next sections explain why.
Other tools complement the border:
- the generated assembly,
asm/main.asm, shows what each line turns into; - the build report and the project diagram in Simple8 IDE give the space used by each unit, in ROM, in RAM and in zero page;
- an emulator debugger (Geargrafx, VICE, Mesen…) counts the cycles
between two points, thanks to the symbol table,
main.sym.
Choosing your types for the processor
In chapter 3, the rule was: the smallest type that does the job. That is true on a 6502, but each processor has its own preferences. Here is the cost of an addition, a multiplication and a division between two variables, measured on the three processor families, in their own units.
6502 (C64, NES, PC Engine): a true 8-bit processor
| Cycles | ubyte | uint | ulong |
|---|---|---|---|
| addition | 6 | 9 | 18 |
| multiplication | 195 | 197 | 693 |
| division | 768 | 770 | 3,145 |
The 6502 computes 8 bits at a time: every extra byte costs. It can neither multiply
nor divide: these operations are small programs, and a ulong makes them 3 to
4 times slower. Prefer ubyte, then uint;
keep ulong for large numbers.
Z80 (Amstrad CPC, MSX, Master System): an 8-bit processor that likes 16 bits
| T-states | ubyte | uint | ulong |
|---|---|---|---|
| addition | 77 | 64 | 383 |
| multiplication | 1,037 | 1,024 | 8,047 |
| division | 2,126 | 2,114 | 12,200 |
Surprise: on a Z80, a uint is no slower than a
ubyte, and even a little faster for addition. The Z80 has 16-bit register
pairs (HL, DE, BC) and a 16-bit addition
(ADD HL,DE): a ubyte, on the other hand, must first be extended.
However, it has nothing for 32 bits: a ulong costs 6 to 8 times more.
On a Z80, uint is the natural type; avoid ulong
in loops. The Game Boy's SM83, a cousin of the Z80, also has 16-bit register
pairs.
The Z80 in practice. Its instructions take longer than the 6502's
(4 T-states at least, often 7 to 19), but each one does more. It has no zero page:
all memory is reached the same way. Its index registers
IX and IY are handy but slow (19 T-states per access). And on the Amstrad CPC, the video chip rounds
every instruction up to a multiple of 4 T-states: the real speed is about 3.3 MHz
rather than 4.
68000 (Mega Drive, Amiga): a 16/32-bit processor
| Cycles | ubyte | uint | ulong |
|---|---|---|---|
| addition | 16 | 16 | 20 |
| multiplication | 72 | 60 | 278 |
| division | 238 | 238 | 432 |
The 68000 has 32-bit registers: an addition costs almost the same for all three sizes.
You might think long is then the natural type. It is not, for two
reasons:
- its multiply and divide instructions only work on 16 bits
(
MULU: 16 × 16 bits;DIVU: 32 bits divided by 16). Aulongmultiplied by aulongtakes several multiplications: 4.6 times slower. Division is almost twice as slow; - its data bus is 16 bits wide: reading or writing a
longin memory takes two accesses instead of one.
On a 68000, int and uint are the natural types;
long is justified when the value goes above 65,535, and for addresses (a
Mega Drive resource is a 32-bit address, chapter 11). ubyte gains nothing
there, and sometimes costs a little more, for the time it takes to extend it.
In summary
| Processor | The most efficient type | Avoid in loops |
|---|---|---|
| 6502, HuC6280 | ubyte | ulong, multiplications, divisions |
| Z80 | uint (or ubyte) | ulong, multiplications, divisions |
| 68000 | uint, int | long in multiplications and divisions |
In every case, unsigned types give the shortest code when the value cannot be negative.
Powers of two
Dividing by a power of two (2, 4, 8, 16, 32…) amounts to shifting the
bits to the right (chapter 3), and taking the remainder amounts to keeping the low bits.
Simple8 does this on its own as soon as the divisor is a constant power
of two. Measured on the C64, with a uint:
| Operation | Cycles | Translated into |
|---|---|---|
i / 40 | 768 | a division routine |
i / 32 | 59 | 5 shifts |
i % 40 | 768 | a division routine |
i % 32 | 1 | an "and": i & 31 |
i * 40 | 82 | shifts and additions |
i * 32 | 62 | 5 shifts |
Dividing by 32 is 13 times faster than dividing by 40, and the remainder by 32 costs almost nothing. Hence a design tip: size things in powers of two. A 64-column map rather than 60, 256-entry arrays, 16 × 16 pixel sprites: index computations become free.
Signed types. With an int, which can be negative, the
compiler shifts too, but adds a correction to round toward zero
(-7 / 4 is -1): 88 cycles instead of 59 for i / 32. Still
far less than a real division.
Zero page and fast
On the 6502: zero page
The 6502 reaches the first 256 bytes of memory faster: zero page.
fast puts a variable there. But not everything gains as much:
| Measured on the C64 | Normal variable | fast variable |
|---|---|---|
incrementing a uint | 30 cycles | 29 cycles |
writing through a pointer, .p[i] = v | 32 cycles | 17 cycles |
For an ordinary variable, zero page saves only one cycle per access. For a pointer, it almost halves the cost: the 6502 can only read through a pointer if it is in zero page, so an ordinary pointer must be copied there on every access.
The optimizer already takes care of it
Zero page is small (206 bytes available on the C64, NES and PC Engine) and shared with
the libraries. The Simple8 optimizer puts the local variables used most in loops there
on its own, without you writing fast. In this program, no
variable is declared fast:
uint f(uint x) {
    uint a = x * 2;
    uint b = a + 1;
    return b;
}
Yet the symbol table shows Main_f_a at $20 and
Main_f_b at $22: in zero page. So every variable declared
fast is a byte the optimizer can no longer give to a loop variable, which is
often more useful.
Depending on the processor
| Machine | Effect of fast |
|---|---|
| C64, NES, PC Engine (6502) | zero page: useful for pointers |
| Game Boy (SM83) | high memory, $FF80-$FFFE, reached by shorter instructions |
| Amstrad CPC (Z80) | none: the Z80 has no faster area, the variable stays at the same address |
| Mega Drive, Amiga (68000) | none: all variables are already placed at $FFFF8000, which the 68000 reaches with a short 16-bit address |
Toward the end of fast
fast is a hint given by hand, and it only makes sense on some processors.
The optimizer already does better for local variables: it measures how they are used,
and chooses on its own. Upcoming versions of Simple8 are meant to extend this automatic
choice to all variables, and fast is expected to disappear. Until then,
keep it for three cases:
- a pointer walked through in a loop;
- a variable read every frame by an interrupt;
- a variable that an
_asmblock addresses in zero page.
Saving memory
| Machine | RAM for the program |
|---|---|
| NES | 2 KB (plus 8 KB on the cartridge, if it has some) |
| PC Engine | 8 KB |
| Game Boy | 8 KB, plus 127 bytes of high memory |
| Commodore 64 | a few KB of variables, within 64 KB shared with the program |
| Mega Drive | 64 KB |
A few rules to go easy on it:
constcosts no RAM. A constant, a constant array or a string stays in ROM. A 256-value table declaredconstsaves 256 bytes of RAM.- An initial value costs twice.
ubyte t[100] = { … };takes 100 bytes of RAM, plus 100 of ROM for the values thatboot.asmcopies there at startup (chapter 3). If the array never changes, make it aconst. - Each local variable has its own place. The locals of two functions do not share the same memory, even if the functions never run at the same time: a large local array in a rarely called function takes up RAM permanently.
- Contexts share their memory (chapter 8): the variables of a level only take up RAM during that level.
- Check the space used: the project diagram in Simple8 IDE gives, for each unit, the ROM, RAM and zero page used.
Recipes
| Rather than… | Write… | Why |
|---|---|---|
| a repeated computation | a const table computed in advance | one read instead of a multiplication (chapter 10: 8 times faster) |
| dividing by 40, 60, 100 | size things in powers of two | 13 times faster |
writeMem(base + i, v) in a loop | a fast pointer: .p[i] = v | no address computation on each iteration |
a ulong just in case | the processor's type: ubyte on 6502, uint on Z80 and 68000 | 3 to 8 times cheaper |
| a function called in a tight loop | its code written into the loop | each call copies its parameters and jumps |
| a recursive function | a loop | no stack to manage (chapter 5) |
| recomputing everything every frame | recompute only what has changed | like the stopwatch in chapter 12, which only writes the seconds when they change |
Readable first. A clear program is easy to fix and to optimize; a program optimized everywhere becomes unreadable. Write it simply first, measure with the border, then optimize the few places that really cost.
Key points
- Everything must fit in one frame: measure with the border before you optimize.
- The right type depends on the processor:
ubyteon 6502,uinton Z80,int/uinton 68000;longis expensive everywhere in multiplications and divisions. - Dividing or taking a remainder by a power of two is almost free: size things in powers of two.
fastis only really useful on the 6502, mostly for pointers; the optimizer already places the most used variables, andfastis expected to disappear.constcosts no RAM; an initial value costs RAM and ROM.
Your turn
- Use the border to measure the cost of a multiplication by 40, then by 32.
Show solutionHide solution
We take the example and change only the computation line: a multiplication instead of a division. To make the band clearly visible, the loop runs 100 times instead of 20. To compare, we compile three versions:
* 40,* 32, and the loop alone (.resultat = i + 1000;), which gives the cost of everything that is not the multiplication.main() { vic.setBackgroundColor(vic.BLACK); while (1) { irq.waitFrame(); // wait for the start of a frame vic.setBorderColor(vic.RED); // the border in red during the computation... for (uint i = 0; i < 100; i++) { .resultat = (i + 1000) * 40; } vic.setBorderColor(vic.BLACK); // ... then in black } }Measured in the test kit's emulator, between the two color changes:
Computation in the loop (100 iterations) Cycles Screen lines Per operation the loop alone 4,954 78 * 4014,354 227 94 cycles * 3211,154 177 62 cycles Multiplying by 32 (five shifts) is still the fastest, but the gap is only 1.5 times, far from the ratio of 13 between the two divisions. The reason: multiplying by a constant does not need a routine. In
asm/main.asm, Simple8 computes 40 = 5 × 8: two shifts and an addition givei * 4 + i, then three shifts multiply by 8. It is division that is expensive, not multiplication by a constant.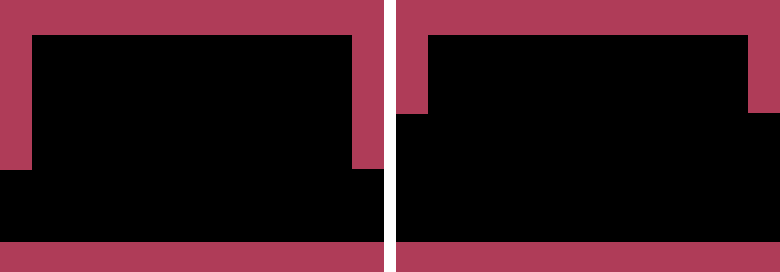
100 multiplications by 40 (left) and by 32 (right), in VICE. The band starts at the bottom of the screen, at the frame interrupt, and continues at the top of the next frame. - Dividing by 40 is often used to find the row of a screen position. Replace the division
in the example with a table of 25 values (the start of each row), and compare the height
of the bands.
Show solutionHide solution
In a program, dividing by 40 is mostly used to find the row of a position on the C64 screen (40 columns, 25 rows, positions 0 to 999). So we change the example to divide real positions, from 0 to 950. The 25-value table holds the start of each row: 0, 40, 80… The row of a position
nis the last one whose start does not exceedn.Walking the table from row 0 works, but gains almost nothing: up to 24
uintcomparisons, nearly the price of the division. The trick is to start from a point that is already close:n >> 6, that isn / 64, only costs shifts and is never larger thann / 40. At most 9 steps remain. Ther < 24test prevents reading past the end of the table.// the start of each screen row: 0, 40, 80… (25 values, in ROM) const uint DEBUT[] = { 0, 40, 80, 120, 160, 200, 240, 280, 320, 360, 400, 440, 480, 520, 560, 600, 640, 680, 720, 760, 800, 840, 880, 920, 960 }; uint resultat; main() { vic.setBackgroundColor(vic.BLACK); while (1) { irq.waitFrame(); // wait for the start of a frame vic.setBorderColor(vic.RED); // the border in red during the computation... uint n = 0; // a screen position, from 0 to 999 for (ubyte i = 0; i < 20; i++) { ubyte r = (ubyte)(n >> 6); // n / 64: never more than the real row while (r < 24 && n >= .DEBUT[r + 1]) { r++; // at most 9 steps to the right row } .resultat = r; // its row, from 0 to 24 n = n + 50; } vic.setBorderColor(vic.BLACK); // ... then in black } } interrupt -> irq { }Measured for 20 positions (the loop alone, without any computation, takes 940 cycles):
Method Cycles Screen lines n / 4016,310 258 the table, walked from 0 14,320 227 the table, from n >> 67,294 115 The band is a little less than half as tall. A check program, which compares the method with
n / 40for all 1,000 screen positions, finds 0 differences. The lesson: a table replaces a computation when you know where to read in it. A 1,000-value table, read directly withLIGNE[n], would be even faster, but would cost 1,000 bytes; this one takes only 50.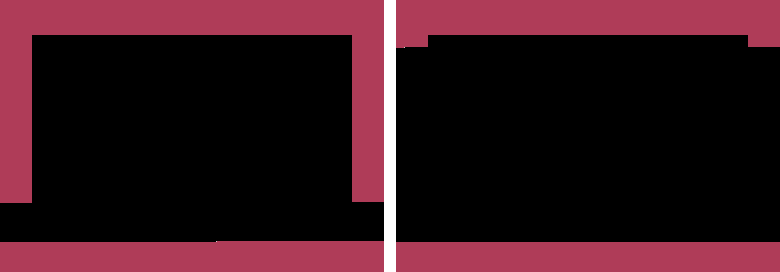
20 divisions by 40 (left) and the table (right), in VICE. - Compile the same program for the C64 and for the Amstrad CPC, with
ubytethen withuint, and compare the code inasm/main.asm.Show solutionHide solution
A short program is enough, as long as it adds, compares and increments. We compile it four times, changing only the architecture and the type (
ubytehere):architecture commodore.c64; unit { ubyte total; main() { for (ubyte i = 0; i < 10; i++) { .total = .total + i; } } }Here is the
mainfunction fromasm/main.asmin each case (the; [Main:L8]lines recall the program line).On the Commodore 64, with
ubyte; [Main:L7] Main_main__FOR_1_i = #0 LDA #<0 STA Main_main__FOR_1_i ; === Loop: _FOR_1 === _FOR_1_start: ; Loop condition: Main_main__FOR_1_i < #10 CMP #<10 BCS _FOR_1_end _loop1: ; [Main:L8] t0 = Main.total + Main_main__FOR_1_i LDA Main_total CLC ADC Main_main__FOR_1_i STA Main_total ; [Main:L8] Main.total = t0 ; Loop increment: Main_main__FOR_1_i++ INC Main_main__FOR_1_i ; Loop end: _FOR_1 LDA Main_main__FOR_1_i CMP #<10 BCC _loop1 _FOR_1_end:On the Commodore 64, with
uint; [Main:L7] Main_main__FOR_1_i = #0 LDA #<0 STA Main_main__FOR_1_i STA Main_main__FOR_1_i+1 ; === Loop: _FOR_1 === _FOR_1_start: ; Loop condition: Main_main__FOR_1_i < #10 LDA Main_main__FOR_1_i+1 CMP #>10 BCC _FOR_1_cond_ok BEQ _FOR_1_cond_ok_skip1 JMP _FOR_1_end _FOR_1_cond_ok_skip1: LDA Main_main__FOR_1_i CMP #<10 BCC _FOR_1_cond_ok JMP _FOR_1_end _FOR_1_cond_ok: ; [Main:L8] t0 = Main.total + Main_main__FOR_1_i LDA Main_total CLC ADC Main_main__FOR_1_i STA Main_total LDA Main_total+1 ADC Main_main__FOR_1_i+1 ; [Main:L8] Main.total = t0 STA Main_total+1 ; Loop increment: Main_main__FOR_1_i++ INC Main_main__FOR_1_i BNE _FOR_1_incr_skip INC Main_main__FOR_1_i+1 _FOR_1_incr_skip: ; Loop end: _FOR_1 JMP _FOR_1_start _FOR_1_end:On the 6502, everything doubles: the addition is done in two steps, low byte then high byte (the second
ADCadds the carry from the first); the comparison with 10 tests the high byte first, then the low byte; the increment must propagate the carry (INC,BNE,INC).On the Amstrad CPC, with
ubyte; [Main:L7] Main_main__FOR_1_i = #0 LD A,0 LD (Main_main__FOR_1_i),A _FOR_1_start: ; Loop condition: Main_main__FOR_1_i < #10 LD A,10 LD B,A LD A,(Main_main__FOR_1_i) CP B JP NC,_FOR_1_end ; [Main:L8] t0 = Main.total + Main_main__FOR_1_i LD A,(Main_total) LD L,A LD H,0 LD A,(Main_main__FOR_1_i) LD E,A LD D,0 ADD HL,DE LD (t0),HL ; [Main:L8] Main.total = t0 LD A,(t0) LD (Main_total),A ; Loop increment: Main_main__FOR_1_i++ LD HL,Main_main__FOR_1_i INC (HL) JP _FOR_1_start _FOR_1_end:On the Amstrad CPC, with
uint; [Main:L7] Main_main__FOR_1_i = #0 LD A,0 LD (Main_main__FOR_1_i),A LD A,0 LD (Main_main__FOR_1_i+1),A _FOR_1_start: ; Loop condition: Main_main__FOR_1_i < #10 LD HL,(Main_main__FOR_1_i) LD DE,10 OR A SBC HL,DE JP NC,_FOR_1_end ; [Main:L8] t0 = Main.total + Main_main__FOR_1_i LD HL,(Main_total) LD DE,(Main_main__FOR_1_i) ADD HL,DE LD (t0),HL ; [Main:L8] Main.total = t0 LD HL,(t0) LD (Main_total),HL ; Loop increment: Main_main__FOR_1_i++ LD HL,(Main_main__FOR_1_i) INC HL LD (Main_main__FOR_1_i),HL JP _FOR_1_start _FOR_1_end:On the Z80, it is the other way around for the addition: with
uint, it takes three instructions (LD HL,LD DE,ADD HL,DE); withubyte, each value must first be extended to 16 bits (LD H,0,LD D,0) before the sameADD HL,DE, then the result is brought back to one byte. The comparison and the increment, however, stay shorter withubyte(CP,INC (HL)).Measured in the test kit's emulators (the program minus an empty program), along with the code size of
main:C64, ubyteC64, uintCPC, ubyteCPC, uintTime for 10 iterations 281 cycles 584 cycles 1,884 T-states 2,602 T-states Size of main25 bytes 52 bytes 44 bytes 49 bytes On the C64, switching to
uintdoubles both time and size. On the CPC, the size barely changes, and the addition itself gets simpler; in this loop, though, the comparison and the increment of a 16-bit counter make the whole thing 1.4 times slower. The Z80 has no preference as clear-cut as the 6502's: you have to look at the code. - In the IDE's project diagram, find the unit that takes the most RAM, and
shrink it with
const.Show solutionHide solution
For each unit, the project diagram shows what the compiler writes to
asm/main_units.json: ROM, RAM and zero page. So you can do the exercise in the IDE, or by reading that file. The course examples already declare their tables asconst; here is a small program that does not: aNiveau(level) unit with a map of 8 rows of 32 cells, and two small tables to draw it.// Niveau.s8u: a map of 8 rows of 32 cells unit Niveau { ubyte carte[256] = { 1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1, 1,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,1, 1,0,2,2,2,2,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,2,2,2,2,0,1, 1,0,0,0,0,0,0,0,0,0,0,3,3,3,3,3,3,3,3,3,3,0,0,0,0,0,0,0,0,0,0,1, 1,0,0,0,0,0,0,0,0,0,0,3,0,0,0,0,0,0,0,0,3,0,0,0,0,0,0,0,0,0,0,1, 1,0,2,2,2,2,0,0,0,0,0,3,3,3,3,3,3,3,3,3,3,0,0,0,0,0,2,2,2,2,0,1, 1,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,1, 1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1 }; ubyte couleurs[4] = { 0, 14, 7, 2 }; // empty, wall, bonus, trap ubyte dessins[4] = { ' ', '#', '*', '+' };The diagram (and
main_units.json) gives, forNiveau:"rom": 355, "ram": 264. It is by far the unit that takes the most RAM:Maintakes none. The 264 bytes are the three arrays (256 + 4 + 4). They have an initial value, so they exist twice: in RAM, and in the program, from whichboot.asmcopies them at startup.But
dessiner()(draw) only reads these arrays. So we declare themconst, with an uppercase name like the other constants in the course, and the size in brackets is no longer needed:unit Niveau { const ubyte CARTE[] = { 1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1, // … 1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1,1 }; const ubyte COULEURS[] = { 0, 14, 7, 2 }; // empty, wall, bonus, trap const ubyte DESSINS[] = { ' ', '#', '*', '+' }; void dessiner() { uint n = 0; for (ubyte y = 0; y < 8; y++) { vic.setCursor(4, (ubyte)(y + 8)); for (ubyte x = 0; x < 32; x++) { ubyte c = .CARTE[n]; vic.setFontColor(.COULEURS[c]); vic.putChar(.DESSINS[c]); n++; } } } }Result:
"rom": 355, "ram": 0. The 264 bytes of RAM are freed, the ROM does not change (the values were already there), and themain.prgfile even loses 18 bytes: the startup copy table has nothing left to copy. The screen is identical down to the pixel (VICE screenshots compared).If one day the game needs to modify the map (a broken brick, for example), it can no longer be
const. You then keep the original map asconst, and put in RAM only what changes, likeJeu.briquesin chapter 14.